Category: LIS4317

  • Module # 9 assignment: Multivariate Visualization

    For this assignment, we are asked to create a multivariate graph, which shows relationships between more than 2 variables. I decided to use RStudios iris dataset, which contains observations of 3 species of iris flowers. It contains 150 observations, and each records four physical features measured in centimeters: sepal length, sepal width, petal length, and petal width.
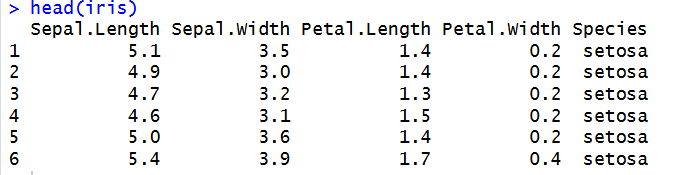
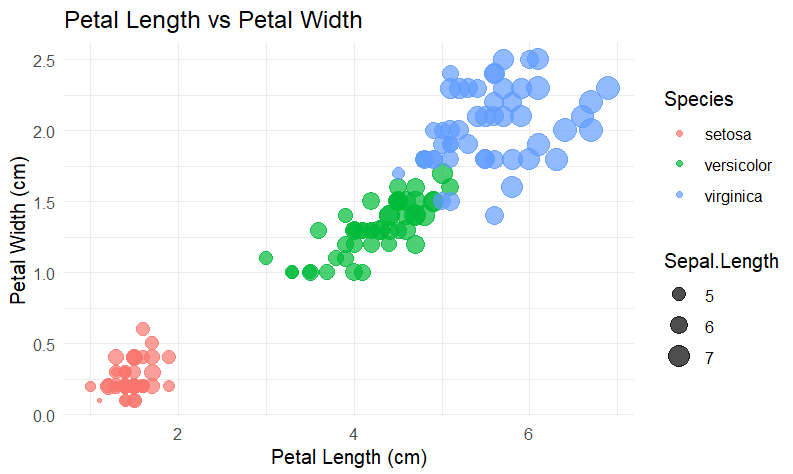
    Using ggplot, I created a scatter plot visualization comparing petal length vs. petal width. The points are color coded by species, and the point side correlated with sepal length. 
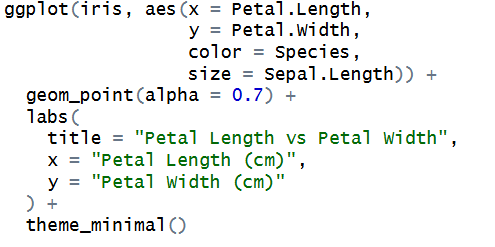
    For my multivariate graph, I used the iris dataset because it comes built into RStudio, and I have been using the mtcars dataset a lot lately, so I wanted to switch it up and try something different. My graph compares petal length, petal width, sepal length, and the 3 different species of flowers. One thing I noticed was that Setosa flowers have the smallest petals on average, Versicolor flowers are a little larger, and Virginica flowers have the largest petals on average. The graph also shows that flowers with longer petals tend to have wider petals as well. I think using a multivariate graph was effective for this dataset because it allowed me to compare multiple variables at once instead of having to make separate graphs for each one. Using different colors for the species and different point sizes for sepal length made it easier to see patterns and differences between the flowers without making the graph too confusing.

    Using different colors for the species creates a contrast that makes it very easy to tell which data points belong to which species of flower. For instance, we can clearly see that the Setosa flowers have a much smaller petal size on average, while Versicolor is larger, but Virginica has the largest petal size on average out of all 3. Proximity was used by how the data points are grouped together based on their petal length and width. Flowers with similar measurements are closer together, which makes it easier to see the similarities and differences between the species. The colors also help connect the points that belong to the same species even if they aren’t right next to each other.  The different colors and point sizes help keep the graph visually balanced, while the labels and legend make everything look more organized and easier to follow.
  • Module # 8 Correlation Analysis and ggplot2

    I will be using Rs built in dataset mtcars in order to explore relationships between variables using correlation or regression analysis and visualize them using ggplot2.

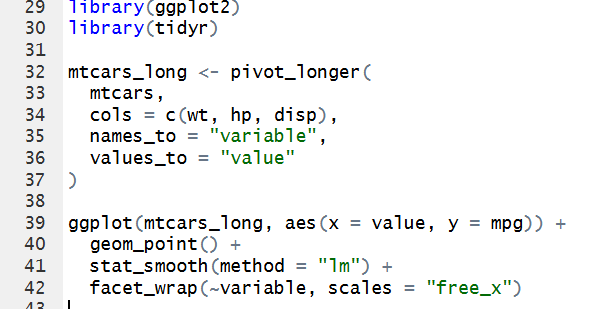
    I will use cor() to compute correlation matrices,  lm() for linear regression models, and ggplot2 for visualizations with geom_point() for scatter plots, stat_smooth(method = "lm") to add regression lines, and  facet_wrap() or gridExtra to arrange multiple plots.

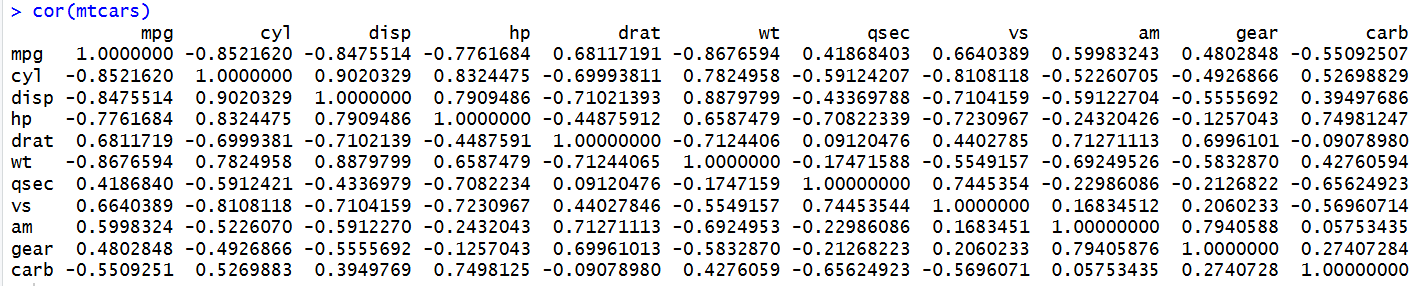
    Correlation values range from -1 to +1. A value of +1 indicates a positive correlation, meaning that when one variable increases, the other tends to increase as well. A value of -1 indicates a negative correlation, meaning that when one variable increases, the other tends to decrease. A value of 0 indicates little or no linear relationship between the variables.

    The cor(mtcars) function calculates a correlation matrix to show the strength and direction of relationships between variables in the dataset. So for instance, the results show a strong negative correlation between  mpg and wt, meaning heavier cars tend to have lower fuel efficiency. There is also a strong negative correlation between mpg and hp, suggesting that cars with higher horsepower generally have lower fuel efficiency. 

    In R, lm() is used to create a linear regression model, which helps us understand relationships between variables and predict an outcome based on one or more predictors.

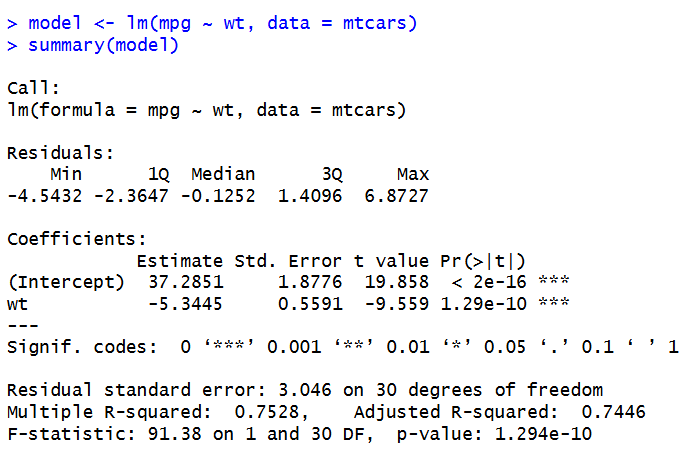
    We can look at the relationship between mpg and wt further:

    The linear regression model shows a negative relationship between car weight and fuel efficiency. The weight coefficient is approximately -5.344, meaning that for every increase of 1,000 pounds in car weight, fuel efficiency is predicted to decrease by approximately 5.34 miles per gallon. The intercept is approximately 37.285, meaning the predicted MPG when car weight is zero. The model has an R squared value of approximately 0.753, meaning that car weight explains around 75.3% of the variation in fuel efficiency in this dataset. It seems heavier cars generally have lower fuel efficiency.

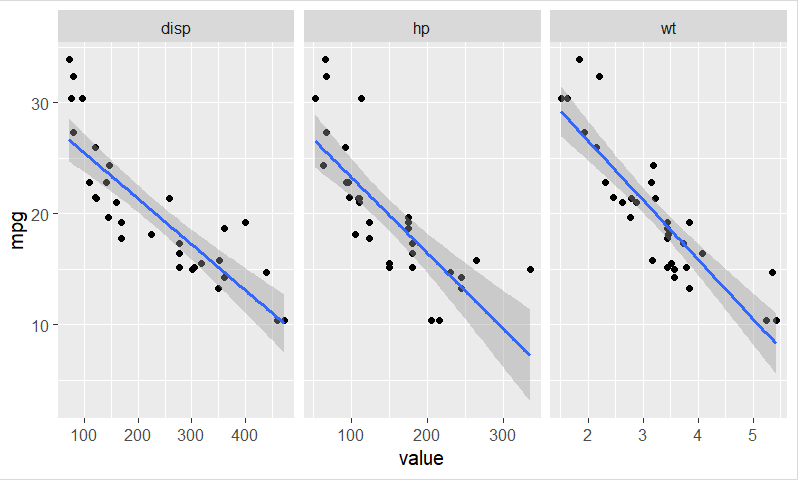
    I created three scatter plots with regression lines to show the relationships between MPG and weight, displacement, and horsepower. In all three , there is a negative relationship, so as these values increase, MPG generally decreases. Heavier cars and cars with higher horsepower or displacement tend to have lower fuel efficiency. Using a grid layout with facets made it easy to compare these characteristics because all three charts are displayed next to each other, making the patterns easier to identify. I also used a relatively neutral color scheme to keep the visuals simple and easy to read, although I kept the regression line blue because I felt it looked better than a gray or more neutral line. I agree with Few’s recommendations for keeping visualizations clear and avoiding unnecessary clutter. However, I think some flexibility is important because a color choice can improve the appearance of a graph while still making the information easy to understand.

  • Module #7 Assignment: Visualizing Distributions in R

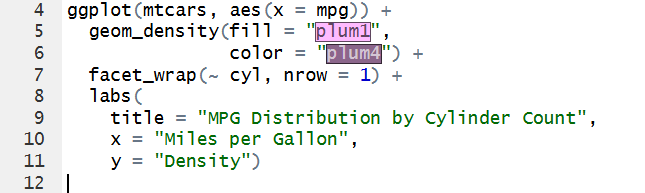
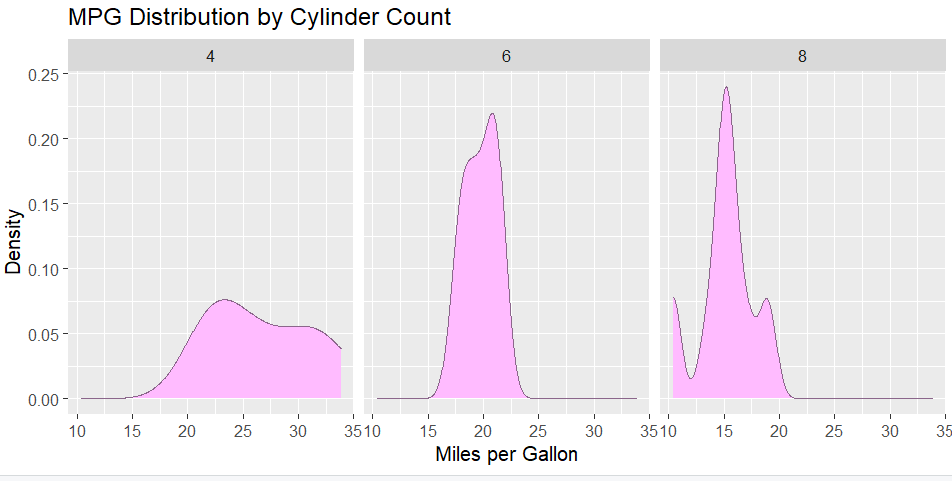
    Using RStudios built in dataset mtcars and ggplot2 , we will be creating  visualizations for distribution analysis. I decided to first create a density plot to see the distribution of miles per gallon across the number of cylinders (4, 6 or 8):

    This visualization shows the spread and distribution of cars MPG by number of cylinders. According to Few, distribution visualizations have 3 key characteristics, spread, center, and shape.

    4 cylinder:

    • Spread between 15-35 MPG
    • Center is a little less than 25 MPG
    • Shape is leaning towards the right and mid to higher values

    6 cylinder:

    • Spread between 15-25 MPG
    • Center is a little above 20
    • Bell shaped, with values close together

    8 cylinder:

    • Spread between 10-20 MPG
    • Center at 15 MPG
    • Has multi modal shape, with value concentrated mostly at 15 MPG, and then 10 and 20 MPG

    Looking at the graphs and these characteristics, we can notice patterns of:

    • cars with 4 cylinders tend to have mid to high MPG of around 20 and above
    • those with 6 cylinders stay in the mid range of 15-25 MPG
    • cars with 8 cylinders tend to have a lower MPG, of 20 and below

    It could be inferred that the more cylinders a car has, the more fuel is consumed. 

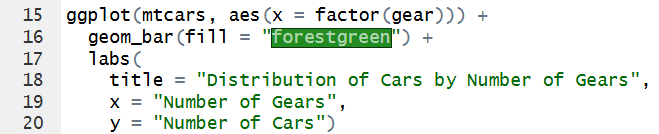
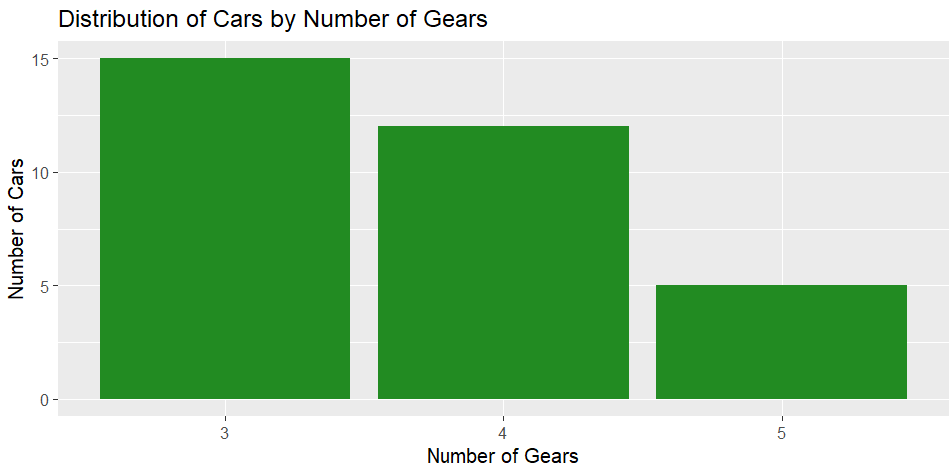
    For a bar plot for categorical distributions, we can look at 

    The graph is skewed to the left, showing a higher distribution of cars having 3 gears, and the number progressively lowering from 4 to 5. 

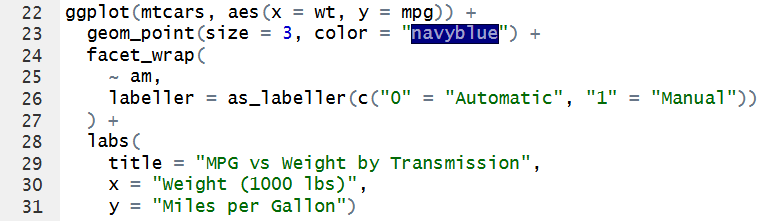
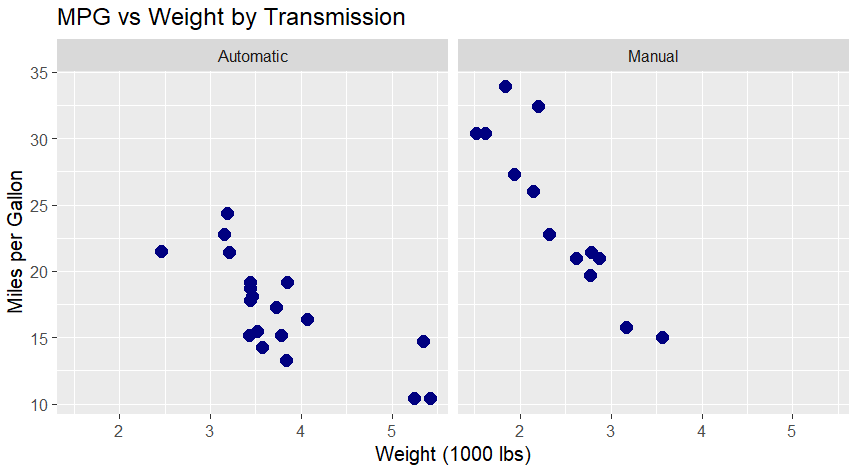
    Finally, for scatter plots, we can compare automatic vs manual transmission MPG by the cars weight:

    Just from looking at this visualization, we can see that manual cars in the dataset have higher MPG the lighter the car is. Automatic cars tend to have a lower MPG, but some automatic and manual cars have similar MPG values, so transmission type alone does not explain fuel efficiency.

    I agree with Few’s critique of how distributions are commonly presented in visual analytics. Using averages can hide important details and fail to show the full picture of the data. I also agree that box plots are not always the best way to visualize distributions because they can hide individual data points and other important patterns. Additionally, our eyes tend to focus on the box, which may lead us to assume that this is where the data is most concentrated, even when that may not be the case.

  • Module # 6 R and graphics with R

    For this assignment, we will be creating basic graphics using R Studio. I will be using R’s built in dataset mtcars.

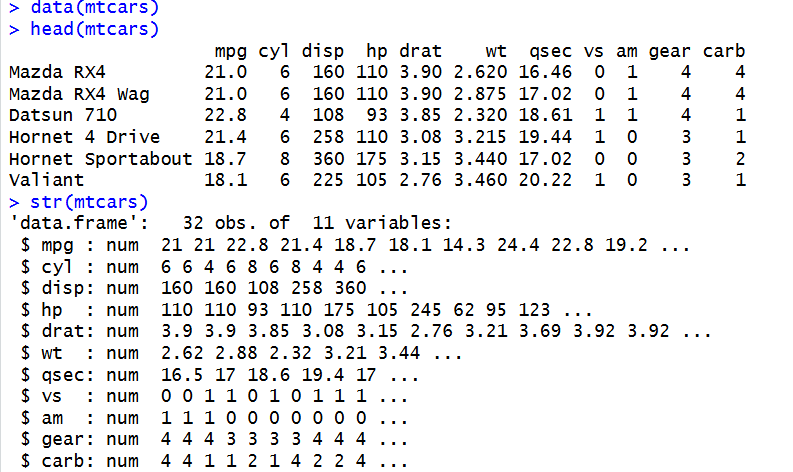
    To start, we will inspect the columns and format of the dataset, and check its structure:

    We can see that there are 11 variables and 32 observations. This means there are 32 car types in the dataset, and 11 different columns of measurements/attributes such as miles per gallon, number of cylinders, and engine displacement. 

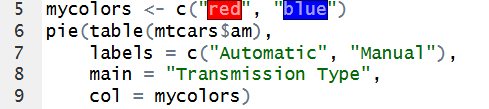
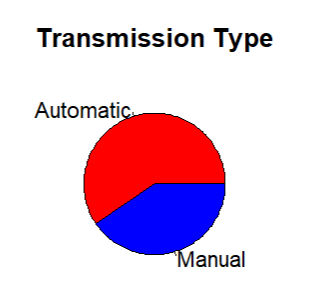
    For a pie chart visualization, I decided to look at transmission type. I will create a pie chart showing what percent of cars have an automatic transmission vs. a manual transmission:

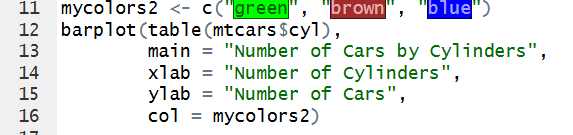
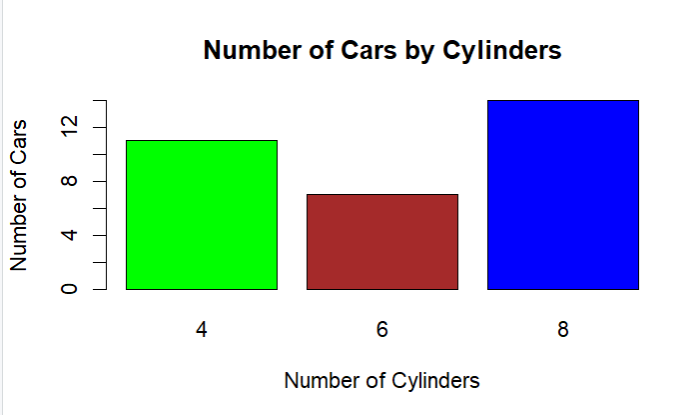
    For a bar chart, I compared the amount of cars with 4, 6, or 8 cylinders:

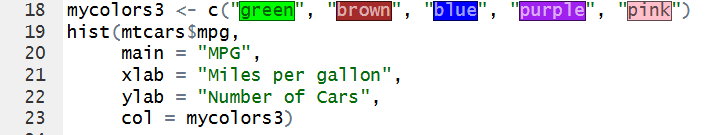
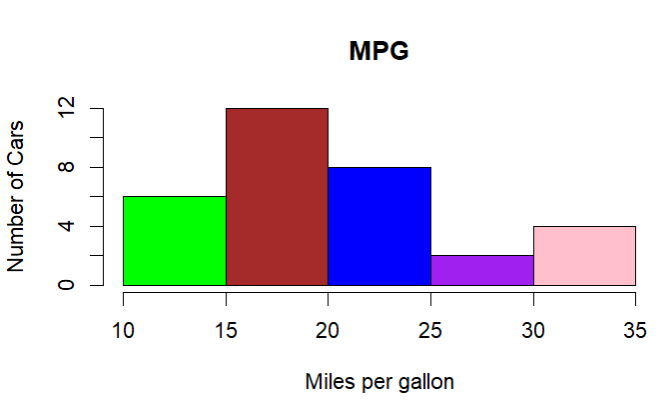
    For the histogram, I’ll compare mpg between cars:

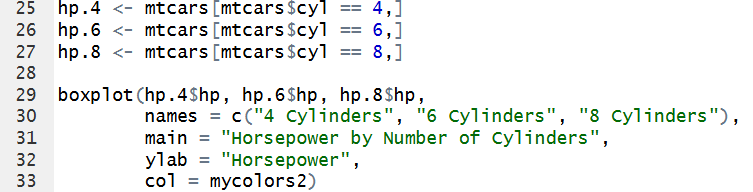
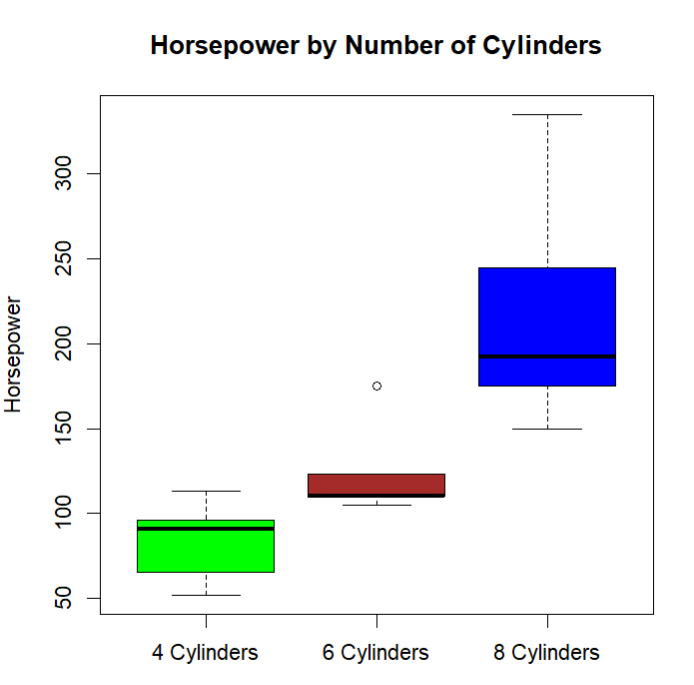
    Finally, the box plots will by showing the relationship between horsepower and number of cylinders:

    In the pie chart, we can easily understand from a glance that there are more automatic cars than manual. The bar chart also clearly shows that most of the cars have 8 cylinders, then 4, and the least amount of cars have 6. The histogram is easy to understand, and its obvious that most cars have a MPG between 15-20, and the least between 25-30. Finally, the box plots also make the trend that more cylinders = more horsepower clear.

    I think these simple visualizations do a good job of communicating the main ideas in the data and are useful for conducting a basic descriptive analysis. The visualizations make it easier to recognize patterns and compare different aspects of the mtcars dataset without having to look through the raw numbers. Some of my choices do not completely follow the recommendations discussed by the authors, however. For example, Yau explains that darker colors are typically used to represent greater values, while lighter colors represent lower values. In my visualizations, I just used different colors to separate categories rather than using color to represent the size of a value, so my charts do not follow this guideline. At the same time, my visualizations do follow the authors’ broader idea that graphs should make comparisons easier for the viewer. Having the box plots and other graphs displayed clearly allows the viewer to compare groups visually. I think the basic visualizations are appropriate for a simple descriptive analysis because they make the patterns and differences in the data easier to understand.


  • Module #5 Assignment: Create Your Own Visualizations

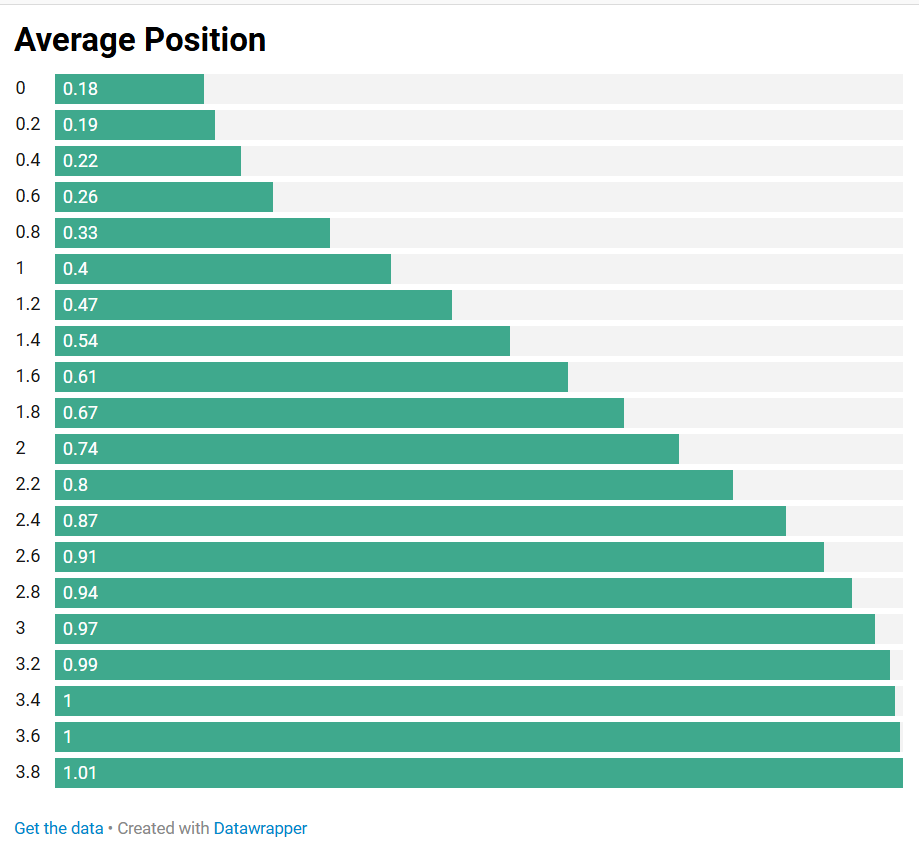
    For this assignment, we are asked to create a ranking chart and a part-to-whole chart, using a given dataset containing Average Position and Time. For the ranking chart, I created an ordered bar chart using Datawrapper:

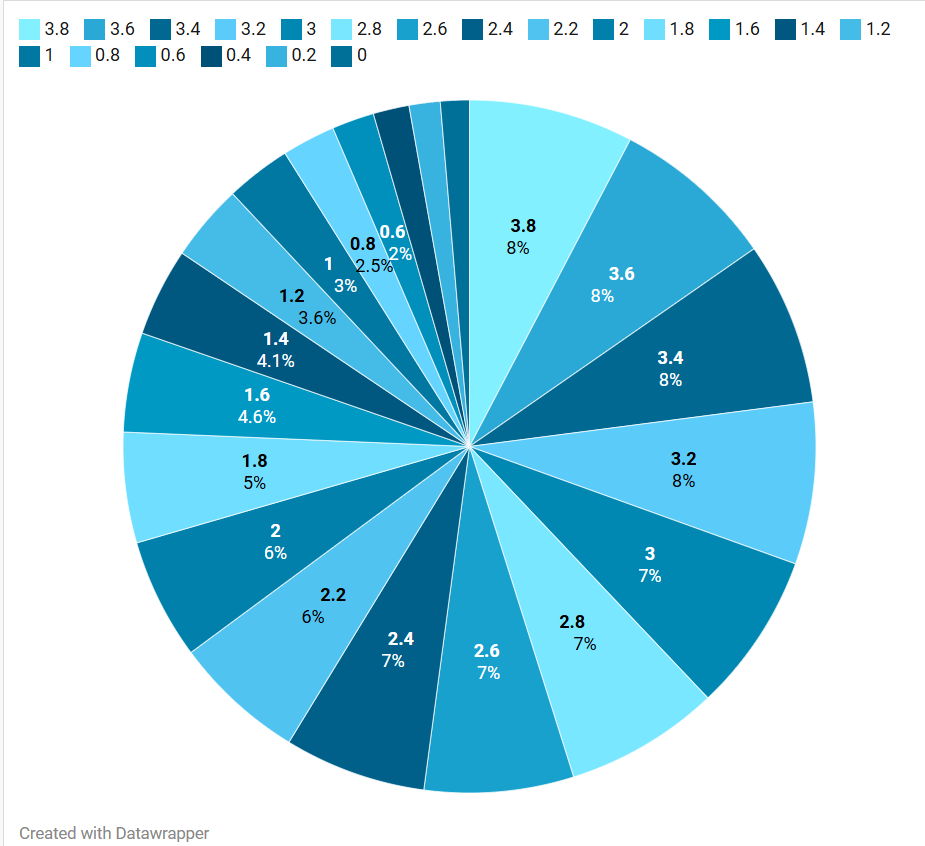
    Then, for the second chart, a part-to-whole visualization, I created a pie chart:

    The ranking chart shows the average position according to the time. Looking at this, we can see that the increase isn’t perfectly linear, starting off slow then increasing more rapidly before slowing down as it reaches 1. The ranking design helps highlight the progression of average position and makes it easy to compare the values across the different time points. This shows that average position generally increases over time, with the most noticeable changes occurring in the middle of the range.

    The second chart shows the average position by time. The pie chart shows the proportion of the total average position represented by each time point. This allows us to see which time points make up a larger or smaller share of the overall average position. However, a pie chart is not ideal for this data because the values represent position over a continuous period of time, rather than separate parts that naturally make up a whole.The Part-to-Whole design does provide another way of viewing the data by showing how each time point contributes to the overall total, which can highlight the time points with larger average positions. However, its main limitation is that it does not show the order or progression of time clearly.

    The ranking chart communicates the trend more clearly, while the part-to-whole chart provides a different perspective on the relative contribution of each time point. This demonstrates that part-to-whole can be useful for showing proportions, but it is less effective when the data represents a continuous trend rather than distinct parts of a whole.

  • Module 4: Time Series Visualization

    This week, we are working with the Monthly Modal Time Series dataset to create a time series visualization using Tableau Public. After looking at the dataset, I decided to keep the 6 variables:

    1. Primary USA City
    2. Year
    3. Vehicle Revenue Hours
    4. Ridership
    5. Collisions with Motor Vehicle
    6. Collisions with Person. 

    I chose these variables because they allow me to compare collision trends over time and across different cities. I can look at changes over time, city comparisons, differences between collision types, and  additional context about each transit system.

    For my visualization, I decided to focus on collisions with motor vehicles and persons over time, based on city. To do this, after uploading my data in Tableau, I created a dual axis line chart. The columns/x-axis is the year, and the rows/y-axis is the number of vehicle and person collisions, and each is color coded. I also added a filter by city. This allows you to see the average collisions of all cities, a few, or just look at each one individually.  Below is the interactive graph, and on the right hand side you can change the city being displayed.

    Link here.

    Looking at the graph across all cities, the first noticeable thing is that collisions with motor vehicles are generally higher than collisions with persons. This difference can be seen when comparing the two lines on the chart, with vehicle collisions usually having higher totals over time. The two types of collisions do not occur at the same frequency in the dataset.

     The more interesting pattern is the spike in 2018, where both collision types rise sharply and vehicle collisions rise the most, and the sharp drop in 2019. The drop however, might be a  reflection of incomplete data for that year rather than a real decline, so I would be cautious about reading it as a true change in collisions.

    When I looked at the cities individually, a 2018 spike was actually not common. Most cities peaked in other years, some in 2016 or 2017, and others stayed fairly steady with no major spikes at all. The 2018 peak in the combined graph is driven mostly by a few large cities that did spike that year and pulled the total up. 

    New York, for example, records roughly 500 to 900 vehicle collisions and about 100 to nearly 300 person collisions per year, while a small city like Bend, Oregon records only 1 to 5 vehicle collisions and often 0 person collisions. Because the large cities have such high counts, they dominate the overall average graph, so the combined trend mostly reflects what happens in the biggest cities rather than a typical city. It is also important to remember that the chart shows collision counts, not rates. A city with more collisions is not necessarily less safe, since it may simply have more people, more vehicles, and more traffic. This is why looking at cities individually, or a few at a time, is more informative than relying on the overall average.

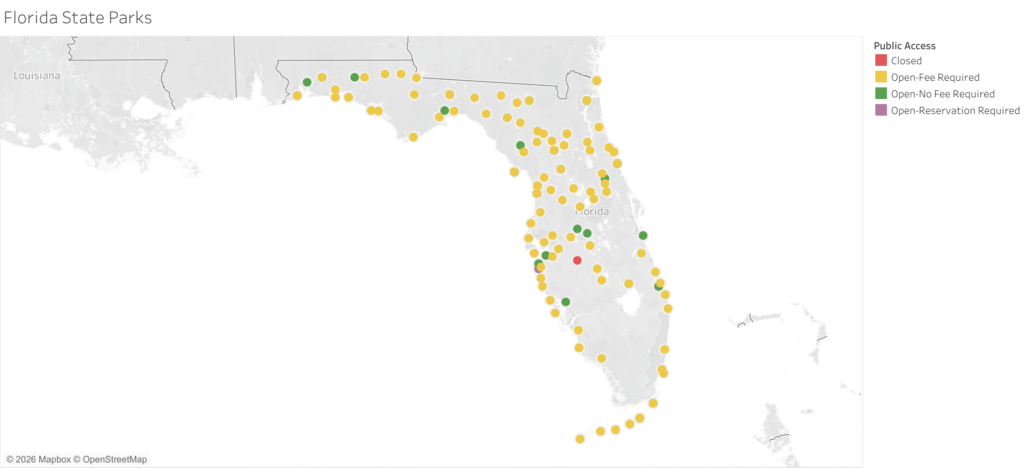
  • Module 2: My Geographic Map of Florida State Parks

    For this assignment, we are asked to find a dataset and use it to build a map in Tableau. For my dataset, I created a visual for Florida State Parks Boundaries from the platform. 

    As I was creating this visualization, I came across some challenges. First, I had to do some basic tweaking, as my dataset did not include longitude and latitude columns. This meant Tableau had to generate them, leading to it creating 150 separate maps, one for each point. This was simple enough though, and I just had to remove the address data from the mapping column. 

    After fixing this and creating one map, it was only plotting about 10 of the points, instead of all of them. This took me a much longer time to troubleshoot, but it ended up being an easy fix. Tableau was grouping the parks together, so I had to manually split the address data into separate city, state, and ZIP data tables. 

    It was also my first time working with Tableau, so the issues I faced took me longer to solve than they should have, since I am still new to the platform and interface. 


  • Assignment # 1: Data Visualization Analysis

    Recently, I came across this chart. It compares China’s 2025, 2026, and the 10 year average oil imports in millions of barrels per day. After the Strait of Hormuz crisis in March, there was a dramatic decline in their oil imports, cutting over 5.5mb/d (the largest amount any country has ever stopped importing oil!).

    Source: https://www.api.org/energy-insights/charts-analysis/china-crude-imports-have-declined

    I believe this chart was created by a human designer rather than generated by AI. There doesn’t seem to be any obvious logical errors or missing elements, and the chart is based off of real world data. While it is possible that the data was entered into a system and the chart was automatically generated, I believe the underlying data was entered in by a person, and that the chart was either designed, analyzed, or reviewed by a human. It seems more likely to be human created or at least human reviewed rather than fully AI generated.

    I am excited to be a part of this course! I have reviewed the syllabus, and understand the grading system, course structure, and the Visual Peer Review Dashboard process.